- W1nge2026-09-26
如题
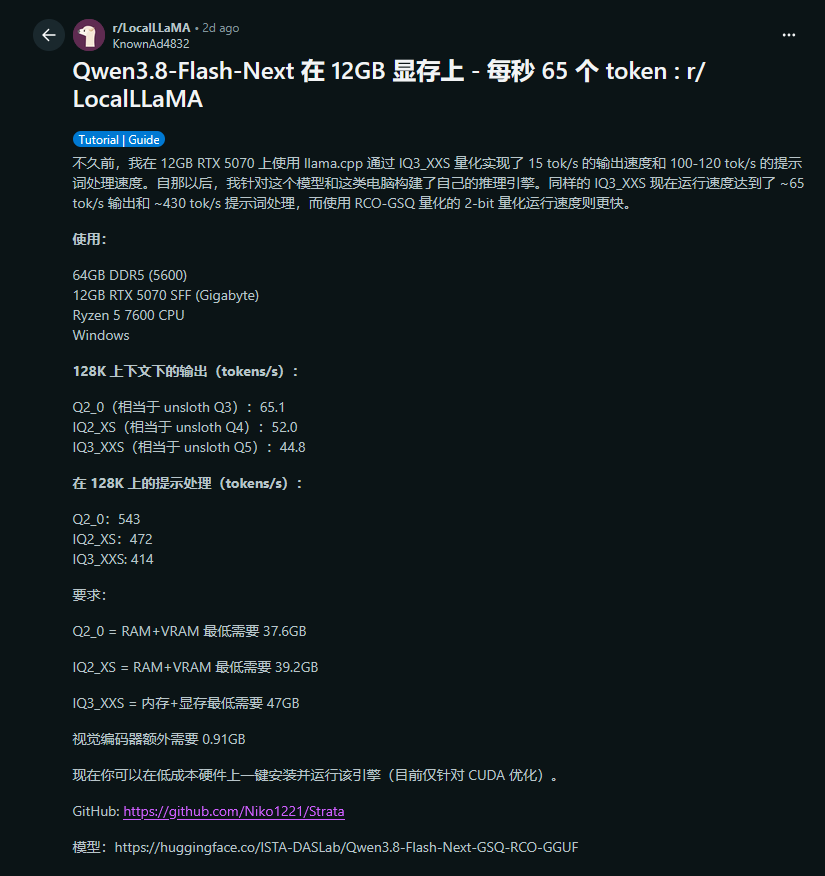
Reddit 老哥给 Qwen3.8 flash next 开发了一个专用推理引擎 Strata
在同样的 5070 12G + 64G 5600内存 + 六核 7600 CPU 配置下能够跑到
Q2_0 → 65.1 tps decode + 543 tps prefill
IQ2_XS → 52.0 tps decode + 472 tps prefill
IQ3_XXS → 44.8 tps decode + 414 tps prefill
与此同时 llama.cpp 的decode只有15tps
老哥Twitter:Niko Veit (@coldniko) / X
Github项目仓库:GitHub - Niko1221/Strata: Qwen3.8-Flash-Next (125B MoE) on a 12-24 GB NVIDIA GPU + 64 GB RAM: one-click install for Windows / Linux. Strata inference engine, OpenAI/Anthropic API on localhost, optional image input. · GitHub
主楼 - sg80112026-09-29
- W1nge2026-09-29
nb啊佬 这个是什么量化的?