- 透眸2026-09-02
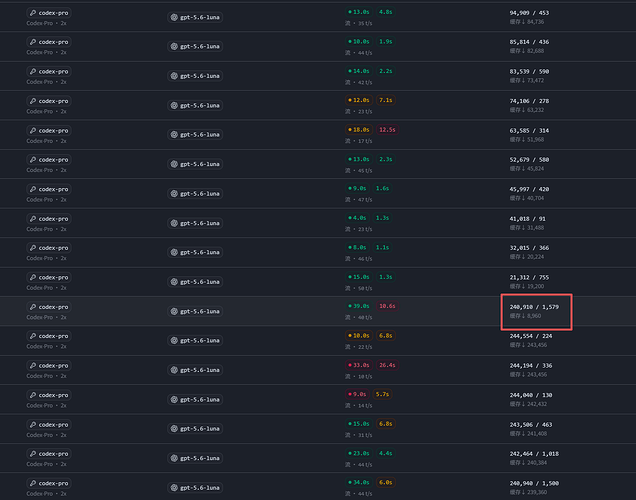
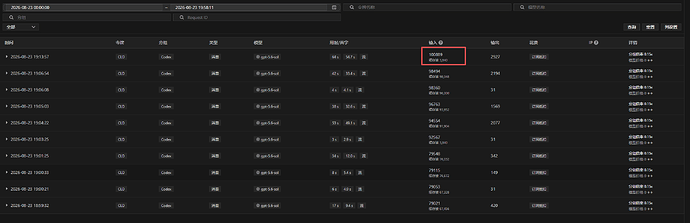 主楼
- 美帝码工2026-09-02
- 白泽2026-09-02
这取决于中转的压缩模型配置吧,我cpa反代的一直都有缓存的
- 透眸2026-09-02
encrypted compaction
我认为剪裁 reasoning 和 tool call 是另一种手段。我记得 openclaw 有。
我说的上下文压缩是指达到上下文阈值后由当前模型根据压缩提示词进行总结。然后开启新会话,填充好 Harness 预设的上下文后,将这次的总结作为新的用户上下文。
已知目前 codex 和 Claude code 都是使用这种方案。
- 透眸2026-09-02
不清楚是裁剪后压缩但是丢缓存(输入少)划算,还是直接压缩(命中缓存)划算。
- 透眸2026-09-02
Claude code 能命中,Codex 不行。
- 美帝码工2026-09-02
- codex 使用的 encrypted compaction 和 claude code 完全不同,不是简单的 prompt based compaction。这是 codex/gpt 目前相比竞品最大的优势之一,能够显著提高长程任务的能力。限制是必须 name 为 OpenAI 或 Azure,否则性能显著下降。大部分中转支持这个功能。```
[model_providers.custom_api]
name = "Azure"
base_url = "<url>/v1"
wire_api = "responses"
```- 看了下源码,compaction 好像不会丢弃 reasoning,那么 cache miss 确实有点奇怪。有可能换了模型给你 compact 不过总不会 luna 换 sol 吧 - 透眸2026-09-02
是个BUG,快一个月了还没修
github.com/openai/codex
Local compaction request omits tool specs, so it never hits the prompt cache (full window re-billed uncached on every compaction)
已打开 05:27PM - 06 Aug 26 UTC
NaruSora
bug
rate-limits
CLI
context
Version / context
codex-cli 0.146.1 (code references pinned to tag
rust-v0….146.1). Affects every provider that takes the local compaction path (all non-OpenAI/Azure providers today; and OpenAI users too if #34428 is fixed by routing custom compact prompts locally).What happens
run_compact_task_inner_implbuilds the summarization request ashttps://github.com/openai/codex/blob/rust-v0.146.1/codex-rs/core/src/compact.rs#L277-L281```rust
let prompt = Prompt {
input: turn_input,
base_instructions: sess.get_base_instructions().await,
..Default::default()
};
``i.e. **withouttools/parallel_tool_calls`**, while every regular turn in the same session serializes the tool specs into the request (see the remote analogue, which does include them: https://github.com/openai/codex/blob/rust-v0.146.1/codex-rs/core/src/compact_remote_request.rs#L63-L70).Prompt caching is prefix-based over the serialized request including tools, so the compaction request's prefix never matches the session's cached prefix. Result: the entire conversation history is re-billed uncached on every compaction.
Measured impact
On a long-running session: compaction triggers at ~235k input tokens and normal turns run 96–99% cached. A prefix-mismatched compaction re-bills the full ~235k uncached each time; across a thread with frequent compactions this added roughly +70% to total uncached input on our workload.
Suggested fix (validated locally)
Mirror the remote request builder: include
tools: step_context.tool_router.model_visible_specs()andparallel_tool_calls: turn_context.model_info.supports_parallel_tool_callsin the local compactionPrompt. We applied exactly this on top ofrust-v0.146.1: compaction requests then hit the prompt cache (65–88% cached even on a small verification session whose uncached tail was dominated by freshly read files), summaries are unaffected, andcargo test -p codex-core --lib compact/--test all compactmatch pristine (54 / 115 passing).Interaction
This compounds with #34428: any fix that makes
compact_prompteffective by routing to local compaction will surface this cost bug for the default provider as well.